Analyze how experimental results and claims are presented, scoped, and limited in a paper.Know what the science actually supports before you trust the answer.
Press Enter ↵ to analyze
Explore by Goal
"In nature, nothing exists alone."
- Rachel Carson
Quick Explanation
Copied
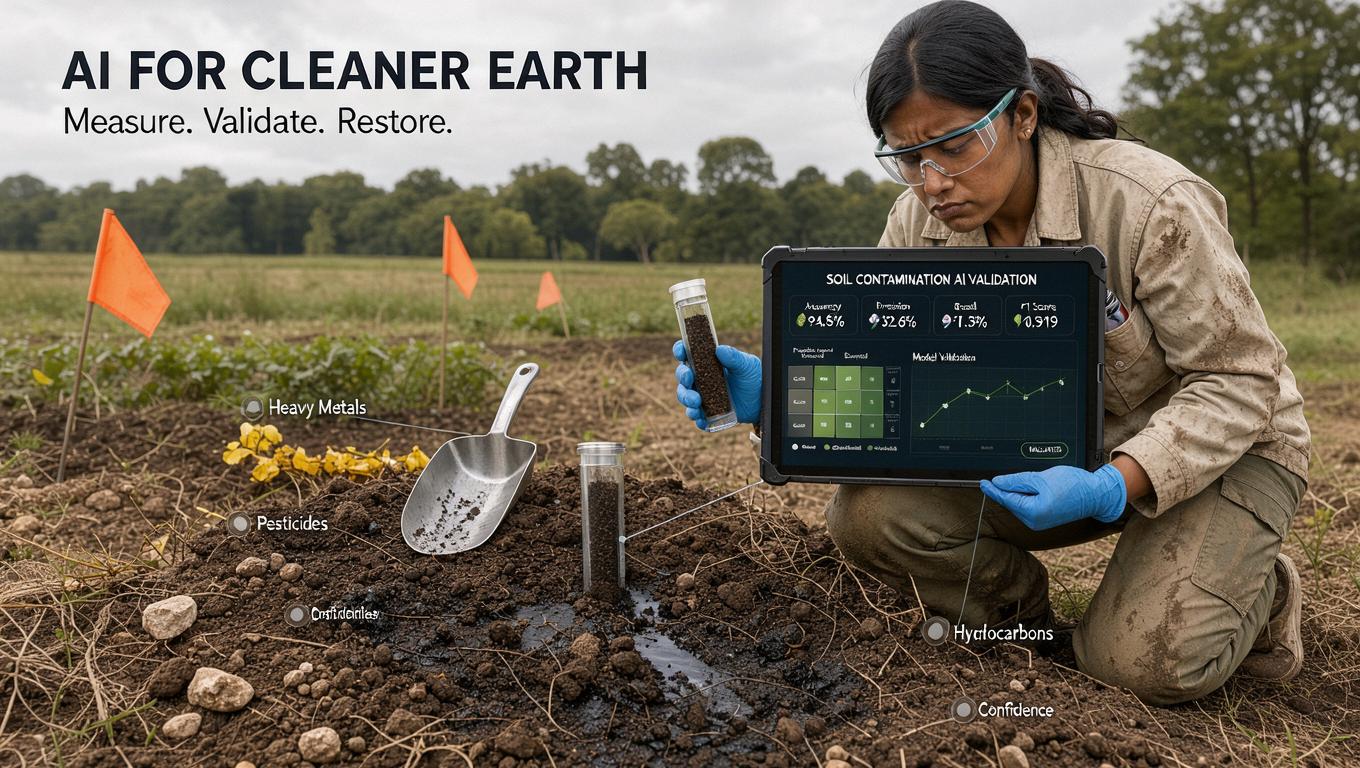
This simulation-only study shows random cross-validation overstated true map accuracy for 19 of 20 synthetic lead-contaminated sites (R² 0.86 vs 0.74 census), spatial-block CV was pessimistic (0.66), and cost-aware decision rules cut missed exceedances from 31% to 5%. The internal logic is sound and well-reported, but every finding is synthetic and untested against field data.
Long Explanation
Core Findings: A Census-Referenced Simulation
The paper uses 20 synthetic 100×100-cell lead-contaminated sites with fully known concentrations (a census no field study can offer) to benchmark three accuracy estimators under preferential clustered sampling
E1 – Validation bias: Random 10-fold CV overstated census R² for every model (gaps +0.12 to +0.26), most severely for IDW (+0.24: 0.93 reported vs 0.70 true). Spatial-block CV was pessimistic for RF (0.66 vs 0.74) and wildly unstable for the neural network (0.09 ± 0.50)
E2 – Sample size: At n=60 the RF census R² was only 0.19 ± 0.42 while random CV reported 0.72 — a gap that closes by n=800 (0.88 vs 0.82). Small studies cannot self-report accuracy reliably under either scheme
E3 – Interval coverage: Nominal 90% conformal intervals covered only 82% (random calibration) vs 94% (spatial calibration); outside the area-of-applicability, coverage collapsed to 64% and 84% respectively
E4–E6 – Decisions, sampling, transfer: Mean-threshold maps missed 31% of exceedance cells regardless of cost ratio; a Bayes rule at r=10 cut misses to 5% (spatial-σ) or 9% (random-σ) at roughly half the cost of the naive threshold. Space-filling maximin sampling gave the lowest RMSE (0.280 at n=300 vs 0.323 preferential), while preferential/uncertainty sampling retained the best exceedance recall (0.69) — no strategy dominated both. Spectral-only models transferred catastrophically to new sites (new-site R² 0.09–0.10; 30–40% negative)
Critical Appraisal
Strengths: Census-grounded ground truth; transparent simulator parameters; both CV schemes bracketed the census value for good models (0.66 and 0.86 around 0.74); Wilcoxon paired tests; four actionable recommendations; full code released.
Blindspots the authors partially acknowledge: all results are synthetic with smooth plumes, one contaminant, no abrupt boundaries, no vertical dimension, or non-point sources; hyperparameters were fixed, not tuned; only 10–20 sites per experiment limits precision (recall SDs of 0.09–0.21 mean most E4 rankings are indistinguishable); hot-spot-local coverage was never evaluated; the Gaussian predictive distribution is an approximation
Unacknowledged concerns: The simulator was authored by the researcher, so linearity/smoothness assumptions could structurally favor tree ensembles; the 120 mg/kg threshold is illustrative, not regulatory; no independent peer review of the codebase is stated; the journal and DOI prefix are non-standard, so indexing/persistence is uncertain. Minor inconsistency: an odd cost-ratio notation "r {1, 2, 5, ∈ 10, 20}" and a truncated table-7 fragment in the text suggest light copyediting. The journal-level self-citation chain (refs 6–9, 27 by the same authors) merits scrutiny for citation-loop dynamics.
Falsification path (authors' own): field studies with independent probability-sample validation where CV schemes fail to bracket census accuracy, or where uncertainty rules fail to cut misses, would weaken the central claims.
Feedback:
Updated: November 02, 2026
BGPT Paper Review
Study Novelty
60%
Combines known components (blocked CV, conformal prediction, AOA, Bayes decision rules) in a new decision-focused census-benchmarked simulation for contaminated soils; the framing is fresh but each ingredient is established.
Scientific Quality
70%
Methodologically transparent, census-referenced, code released, limitations candid. Held back by fully synthetic data, researcher-built simulator, fixed hyperparameters, small site counts, minor copyediting errors, and a self-citation chain.
Study Generality
40%
Conclusions are explicitly scoped to smooth-plume, single-contaminant synthetic sites; real-site generalization is untested, though the validation-methodology message generalizes conceptually.
Study Usefulness
70%
Four concrete recommendations (report both CV schemes, pass uncertainty to decisions, publish AOA, require local calibration) directly change practice for soil-mapping practitioners.
Study Reproducibility
80%
Descriptive benchmarking without mechanistic theory; why spatial CV is pessimistic or why k-means sampling degraded late is not formally explained.
We'll email you the results when your analysis is finished.
Hypothesis Graveyard
'Spatial-block CV is always the safer estimator' — the paper shows it is pessimistic and unstable for ANN (0.09 ± 0.50), so neither internal scheme is universally reliable.
'Active learning always improves maps' — uncertainty-driven sampling failed to beat random sampling on RMSE here, contrary to common active-learning assumptions.

 Explore by Goal
 Quick Explanation
 Long Explanation
 Top Data Sources
 Ask a Follow-Up
 Key Insight
 Keep Exploring
 Hypothesis Graveyard
 Potential Experiments
 Discussion
